The problem
Price-change feeds need a queryable representation that retains the version associated with each input file. This repository connects file parsing, document storage and an HTTP query boundary.
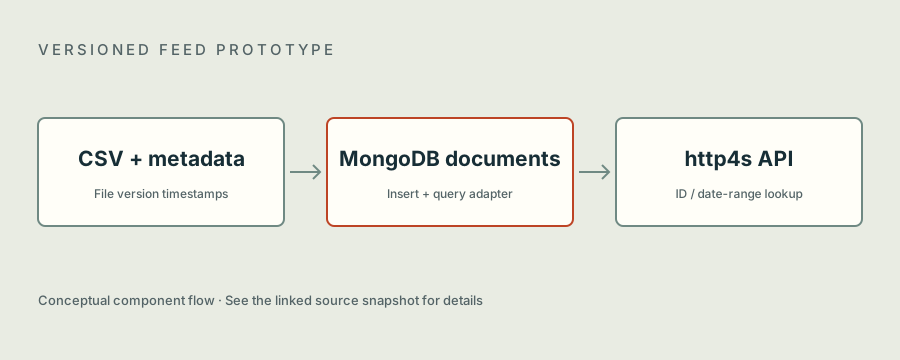
Conceptual summary of the components visible in the source; not a deployment diagram.
What is inside the repository
File-based ingestion
FileHandler reads JSON feed metadata and CSV records. MainFileProcessor adds a version timestamp to each document and contains base/delta feed checks and a day-grouping helper.
A functional application boundary
The entry point is a Cats Effect IOApp; Resource is used around files and the Mongo wrapper. Traversal code expresses parallel work over feed entries.
A small query API
http4s routes query by document ID or by ID plus a date interval. The Mongo wrapper translates the interval into version-field predicates.
Test sources and data fixtures
APIIntegrationSpec uses MongoDB Testcontainers and defines ID/date-range scenarios. FileProcessorTester covers metadata, grouping and CSV parsing with example resources.
What this project demonstrates
End-to-end data flow
Connecting ingestion to a usable downstream API.
Scala effect-oriented design
Using IO, Resource, IOApp and http4s in a data-oriented application.
Engineering judgment
The prototype makes asynchronous completion, replay semantics and reproducible configuration useful next review targets.
These are observations about the code and its relevance to engineering work, not claims of production deployment, measured business impact or exclusive authorship.
Inspect the implementation
These links point to the reviewed commit, so the description can be checked against a stable source snapshot.
src/main/scala/com/cimri/MainFileProcessor.scala ↗
Versioned feed processing entry point
src/main/scala/com/cimri/fileprocessor/FileHandler.scala ↗
JSON/CSV resource handling
src/main/scala/com/cimri/db/MongoWrapper.scala ↗
Database inserts and ID/date queries
src/main/scala/com/cimri/api/Endpoints.scala ↗
Public query routes
src/test/scala/com/cimri/APIIntegrationSpec.scala ↗
MongoDB-backed API test definitions
src/test/scala/com/cimri/FileProcessorTester.scala ↗
File-processing test definitions
Verification and reproducibility
The ingestion, API, database adapter and test sources were inspected. The suite was not run. Test files exist, but their presence is not evidence of passing execution.
Repository command to start with
sbt test
Use the repository README for prerequisites and setup. A listed command is not a promise that an unprepared environment will pass its tests.
Limitations and useful next steps
- The insert methods subscribe to Mongo observables and return IO[Unit] without awaiting database completion; durable completion and error propagation are not established by those effects.
- The current entry point and file tests contain machine-specific paths, and the date-range test formatting differs from the endpoint format.
- CSV input is read fully into memory. The project does not establish bounded-memory ingestion, replay safety or exactly-once effects.
What would strengthen the evidence
- Bridge database completion/errors into IO and make connection ownership explicit.
- Replace absolute paths with fixture/config inputs; add date parsing, duplicate replay and partial-failure tests.