Professional experience at blu Bank. This summary describes responsibilities and technology use, not a public release of the bank’s architecture.
The context
Banking data workflows need to move transaction and profile changes into downstream systems. My work at blu Bank combined real-time consumption with incremental ingestion and orchestration.
My contribution
I built Kafka consumers in workflows sending transaction and profile data to PostgreSQL and MongoDB. I also worked extensively with Python and Faust for incremental ingestion and used Apache Airflow for orchestration, with some additional PySpark work.
Engineering considerations
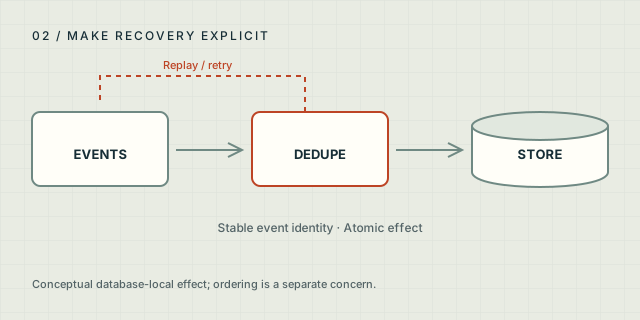
Data movement requires decisions about failures, retries and the relationship between consumption and persistence. The right design depends on the source, destination and recovery requirements.
- Define what happens when processing or a database write fails.
- Understand the effect of repeated delivery on downstream state.
- Make ingestion progress and orchestration dependencies observable.
- Keep operational recovery understandable to the team.
What this experience demonstrates
This work developed my ability to implement ingestion across languages and storage systems and to connect application-level processing with data engineering workflows.
It is the foundation of my interest in replay, idempotency and failure recovery. The conceptual articles on this site explore those topics without claiming they document a specific proprietary implementation.