The problem
A transaction report requires several business transformations to agree: selecting the reporting date, matching registered receivers, applying exchange rates and allocating values to guarantors.
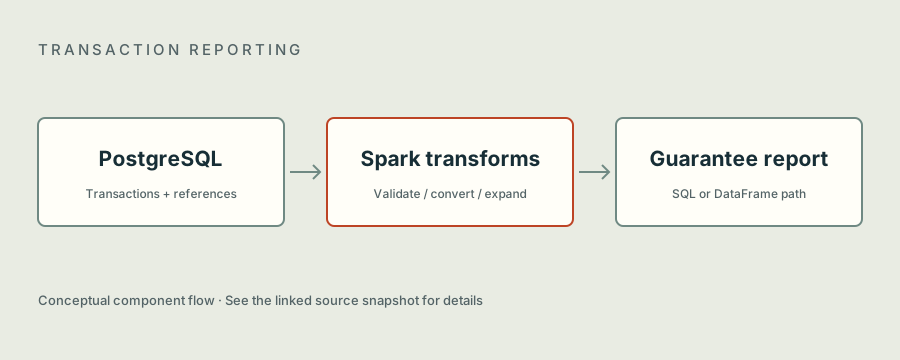
Conceptual summary of the components visible in the source; not a deployment diagram.
What is inside the repository
Two implementations of the reporting flow
SparkApiReport composes named business transformations. SparkSqlReport registers source views and runs SQL before writing typed guarantee records back through the PostgreSQL connector.
Named business modules
Receiver registry checks, euro conversion, guarantor parsing and transaction-class pivoting live in separate source files rather than one opaque entry point.
A JDBC boundary
Repository and connector classes read PostgreSQL source tables and write the resulting guarantees table. Small reference data is broadcast in the inspected transformation code.
Tests that state expected outputs
ReportSpec uses a Docker Compose PostgreSQL container and exercises both reporting implementations. Its assertions include the output row count and selected guarantor totals and averages. BusinessSpec and DataSpec cover additional behavior.
What this project demonstrates
Financial transformation modeling
Turning a domain requirement into named stages and explicit expected output.
Spark fluency
Using both typed/DataFrame operations and SQL for the same reporting task.
Integration-test design
Testing pipeline output against a real database fixture rather than only mocking every dependency.
These are observations about the code and its relevance to engineering work, not claims of production deployment, measured business impact or exclusive authorship.
Inspect the implementation
These links point to the reviewed commit, so the description can be checked against a stable source snapshot.
src/main/scala/SparkApiReport.scala ↗
DataFrame-oriented orchestration
src/main/scala/SparkSqlReport.scala ↗
SQL-oriented reporting entry point
src/main/scala/business/EuroExchangeRates.scala ↗
Reference-data join and conversion
src/main/scala/business/ParseGuarantors.scala ↗
Guarantor expansion
src/test/scala/ReportSpec.scala ↗
Both report paths and expected output assertions
src/test/scala/BusinessSpec.scala ↗
Business transformation tests
-
Actual Scala/Spark and testing dependencies
Verification and reproducibility
Source and test definitions were inspected. The Scala/Spark/PostgreSQL test suite was not executed in this portfolio review; no passing CI run, performance benchmark or regulatory compliance result is claimed.
Repository command to start with
sbt test
Use the repository README for prerequisites and setup. A listed command is not a promise that an unprepared environment will pass its tests.
Limitations and useful next steps
- This is a public code sample, not evidence of a deployed bank system or regulatory sign-off.
- Amounts in the inspected conversion path use the existing transaction model; precision, rounding and missing-rate policy deserve explicit financial fixtures.
- The test harness mutates environment variables through reflection and needs validation on the intended JDK. README setup commands should be checked against the actual build and paths.
What would strengthen the evidence
- Add exact decimal/rounding, missing-reference and effective-date boundary tests.
- Run both implementations in CI against the same independent expected dataset and publish the report.